Stop treating your context window like a garbage disposal
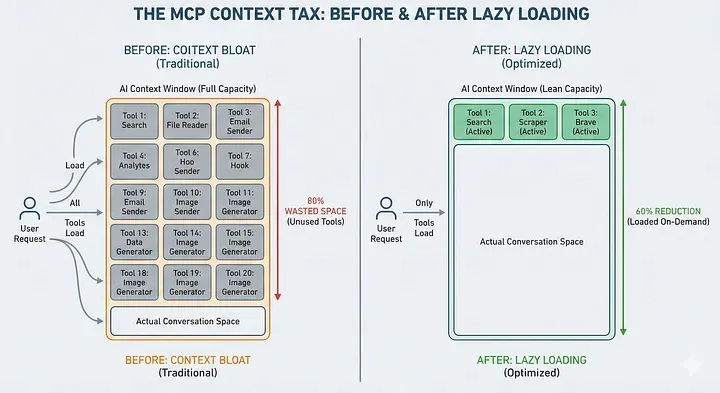
tl;dr: using lazy loading and semantic priority dropped my weekly MCP bill from 4000rs ($47) to around 1000rs ($12). same personal agent, same capabilities, just way fewer wasted tokens. if you’re building agents for side projects and haven’t done this, you’re literally burning your student budget for no reason.
how do you actually fix it?
Lazy Loading: Don’t dump all your tools into context upfront. Load them only when they’re actually needed. I had 23 tools in my personal agent, but most tasks only used 3 or 4. Forcing the model to read all 23 descriptions every single time was just a complete waste of context.
on_conversation_start:
  tools = []  # nothing loaded

on_user_intent("search"):
  tools += [brave_search, scraper]

on_user_intent("files"):
tools += [reader, writer]Semantic Priority: Stop using FIFO for context management. Old doesn’t mean unimportant. Score each item instead: your original research question should always stay, while a random tool output can be compressed or dropped when space gets tight.
context_priority:
  system_prompt: 1.0 (never drop)
  user_request: 0.9 (rarely drop)
  tool_output: 0.4 (compress hard)
intermediate_reasoning: 0.2 (summarize)When context fills up, drop low-priority items first. Not the oldest items.
where are the tokens actually going?
A huge chunk of your budget disappears before the model even does anything useful. Tool outputs return:
- Tiles and snippets
- Raw URLs
- Timestamps and metadata
- Massive JSON payloads just for a simple query
Context isn’t free storage, and it adds up insanely fast.
why do these patterns work?
Lazy loading works because conversations are predictable. If you say “find me papers”, you only need search tools. If you say “update my notes”, you only need file tools. Stop loading things you won’t use.
Semantic priority makes sense because simple FIFO ordering is terrible. Not all messages matter equally.
“I need this for my XYZ project” from early in the conversation is way more important than some random tool output from much later.
Keep the good stuff, drop the noise.
what about the compression layer?
Every tool output gets summarized before it goes back into context. If a search returns 10 results, I keep the top 3 titles, 3 URLs, and a short sentence of insight. The full results are stored locally if I ever need them later.
two quick bonus tips
Look, I know newer models are getting much more optimized at handling huge context windows, but I still highly recommend two things:
- Strictly maintain a
PROGRESS.mdfile. Let the agent update this file every time it completes a checklist item. It stops you from relying on the agent’s internal context compaction, and prevents it from having to re-read the whole conversation history when context eventually drops. - Break up your
AGENTS.mdfile. Instead of creating one giant rule file for your project, use multiple focused files and just source them into your mainAGENTS.md. The agent won’t get confused by a giant wall of text, and you can easily reuse those smaller rule files across all your other projects.
That’s it.